Skip to content

Melvin Tjon Akon

Category: Geen categorie

QNL #5: Dutch Case Law Brief, January 1 – January 14

Posted on 01/21/2016 - 01/21/2016 by mtjonakon

The QNL will now be biweekly instead of weekly, to have a sufficient large number of cases to deal with. In this post, I provide a short overview of the main statistics in terms of cases by institution, by area of law and by throughput time.  This week’s novelty: a text-based, bottom-up classifier, instead of relying on the official judicial classification.

Cases by institution

INSTITUTIONS

The Council of State (RVS), Supreme Court (HR) and the Central Board of Appeal (CRVB) lead the charts. Again, it must be noted that the 28 of the Supreme Court cases are RO 81 cases. A relatively high number of cases was issued by the Court of First Instance of Aruba (OGEAA), a total of 33.

Cases by area of law

AREAS

Keeping my promise of introducing a novelty each QNL, this time a present a new classification. Instead of relying on the official classification, I classified the cases using a text-based, multi-attribute index (see Neshatian & Hejazi for an example). Especially useful for corporate finance lawyers are the ‘finance’ and ‘insolvency’ classes. What’s salient this week, is the number of administrative law decisions, compared to other areas. The three finance-related decisions, issued by the Court of First Instance of Rotterdam (RBROT), involve the Dutch Central Bank in its capacity of financial markets supervisor.

Cases by Throughput Time

TT

The supermajority of all 411 cases is published on the same day or the day following the verdict. Among the outliers of this QNL are the aforementioned cases involving the Dutch Central Bank.

Next QNL

In the following post, I would like to spend time exploring the use of probabilistic language processing models on case law.

Posted in Geen categorie

QNL #3: Dutch Case Law Brief, November 2-8, 2015

Posted on 11/14/2015 - 11/16/2015 by mtjonakon

In the first week of November, the Dutch courts collectively adjudicated more civil law cases than administrative law or criminal law cases. A total of 370 cases has been issued. Just like the previous week, the Raad van State (RVS) issued the highest number of opinions.

Number of cases per institution

The Raad van State (RVS), Centrale Raad van Beroep (CRVB) and the Supreme Court of the Netherlands top the list of number of opinions per institution:

decisions by institution

However, at the aggregate level, the courts of first instance issued the highest number of opinions in contrast to the appellate courts and higher judicial bodies:

decisions_by_institutionallevel

A closer look at the opinions of the Supreme Court reveals that 21 of the 45 are in fact article 81 RO cases. I will introduce a quantitative measure to distinguish between different types of rulings issued by the Supreme Court in the next post.

Cases by area of law

In contrast to last week, the judiciary issued relatively more opinions in the areas of civil law than in criminal law, closely followed by decisions in the areas of social security and administrative law:

decisionsbyarea

Throughput time

This week features a number of decisions published with longer throughput times. In particular, decisions by RVS and CRVB in the areas of social security and immigration law (published 6 days after the decision):

tt

Text analysis of civil law and tax law cases

The corpus of opinions in the areas of civil and tax law is at present too small perform a reliable statistical analysis by training and implementing a classifier. I leave this for the next post.


Posted in Geen categorie

QNL #2: Dutch Case Law Brief, October 26 – November 1, 2015

Posted on 11/09/2015 - 11/09/2015 by mtjonakon

In this QNL, I assess rulings issued by Dutch legal institutions published on www.rechtspraak.nl during the last week of October 2015 using Python‘s natural language processing, data analysis and machine learning packages.

Number of cases by institution 

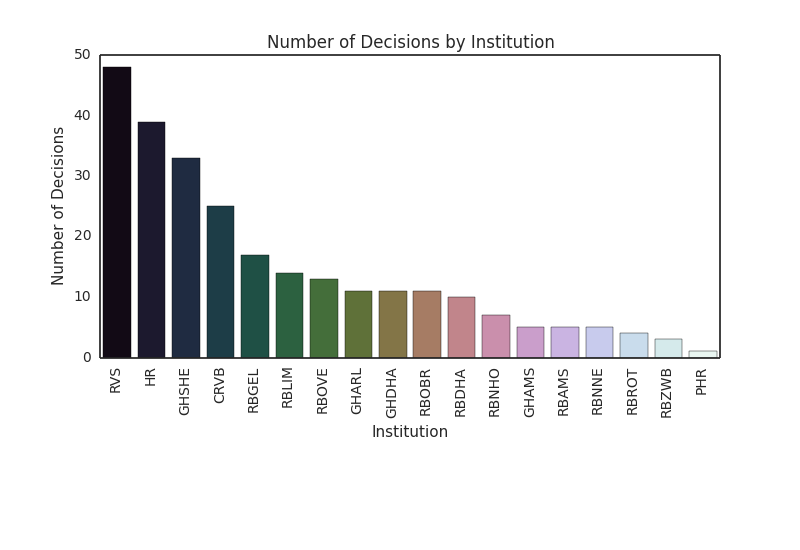
Between October 26 to November 1, 2015, a total of 262 new court rulings were published (list), according to a request via the site’s API. The graph below shows the number of rulings per issuing instution.
METRIC 1 - TOTAL INSTITUTIONS

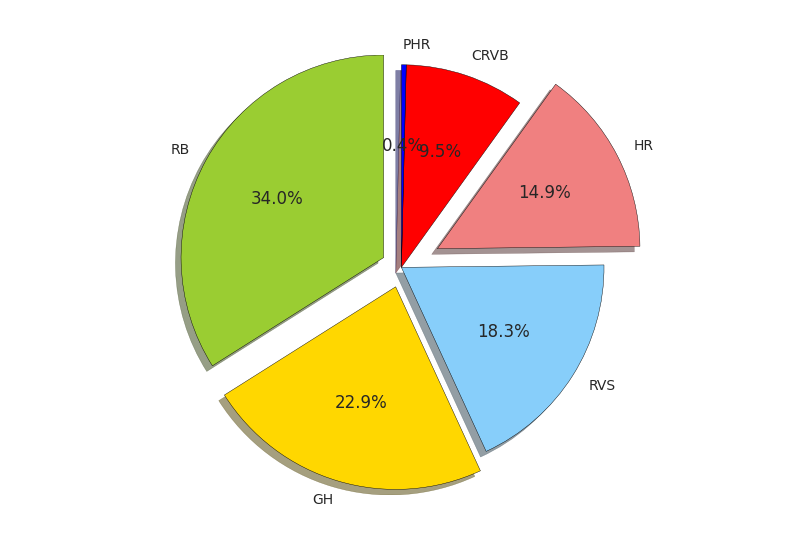
The Council of State (RVS, Raad van State) issued the highest number of rulings (48), followed by the Supreme Court (39) and the Appellate Court of ‘s-Hertogenbosch (33). Summing by institutional level, a predictable pattern emerges. The courts of first instance issued the greatest number of decisions, followed by the appellate courts. The relative shares are shown below.
METRIC 4 - DECISIONS BY LEVEL

Although the Attorney General (‘procureur generaal’, art. 111 Wet op de rechterlijke organisatie) technically is not an independent judicial body and only issues writes advisory opinions, I include those opinions in the analysis. The advisory opinions of the Attorney General are authoritative in Dutch legal circles, as they often provide guidance for judges at the trial and appellate levels.

It should be noted that the most rulings issued by the Supreme Court (22 of 39) are “article 81 RO” rulings. In such a ruling, the Supreme Court decides that (1) neither the appellant’s complaints are sufficient to warrant reversal of the appellate court’s decision,  (2) nor is publication of the Supreme Court’s decision required for the sake of legal uniformity or development of the law. In addition, in a smaller number of rulings (4 of 39), the Supreme Court dismissed the complaint for inadmissibility. 

Number of institutions by area of law

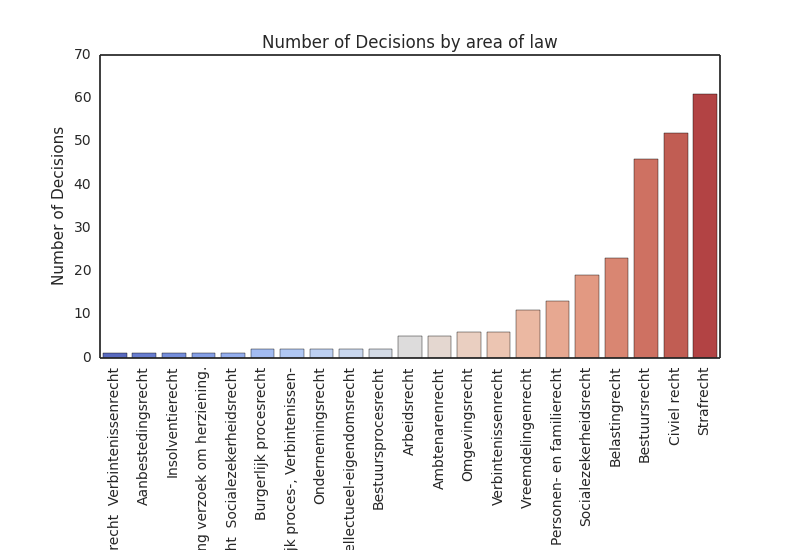
This week, most rulings involved criminal law (61), followed by civil law (52) and administrative law (46). As discussed in a prior post, most cases tend to fall in these general areas of law, rather than more narrowly defined areas such as employment law (5) and business law (2). However, any 1L (first year law student) knows that it’s not the category that matters, but the legal principle discussed (see more below). A graph with the legal categories and frequency counts for this week is posted below.
METRIC 2 - DECISIONS BY AREA

Throughput time

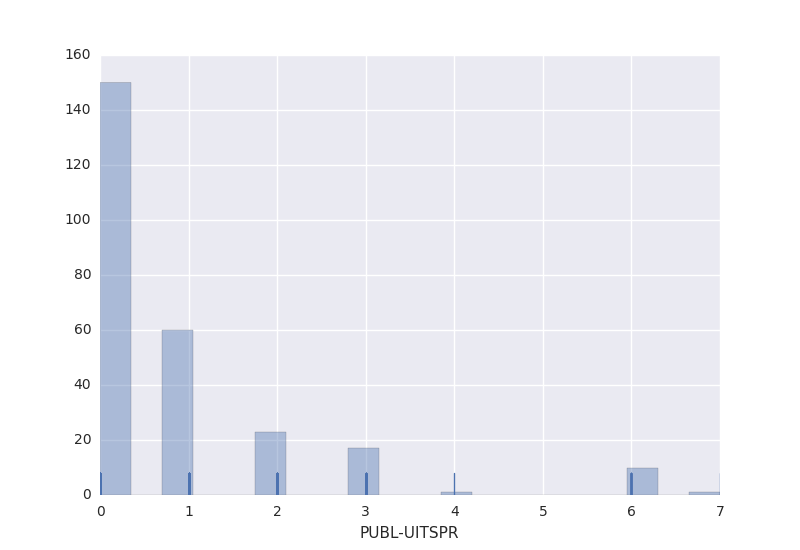
How much time elapses between the decision date and the publication date?
METRIC 3 - THROUGHTPUT

Most cases are published on the date of the actual decision (150 of 262 or 58%), but in 38% (100 of 262) of the cases it takes 1-3 days to publish the decision. If it took 1 day, it was most likely the Appellate Court of ‘s-Hertogenbosch (GHSHE, 22) or the Central Council of Appeal (CRVB, 13). A salient fact is that those courts handled a disproportionately large number of family law (GHSHE) and social security law (CRVB) cases. It’s merely salient: I did not compute any correlations between area of law and throughput time, which would be a poor measure for several reasons.

N-gram analysis

The analysis of n-grams are a fundamental element of any data analysis involving text. Roughly speaking, n-grams are sets of words that occur in the text, consisting of one (unigram), two (bigram) or three (trigram) words. In an n-gram analysis, the documents of the corpus are converted to a matrix with a vector for each n-gram, which facilitates the application of quantitative clustering or classification techniques (in combination with NLP tools such as a lemmatizer). The matrix can contain interesting information, such as the Most Important N-Gram (MING). With the MING approach, textual differences and similarities become apparent. Prior to using MING to classify texts (future posts), let’s contrast the most frequent unigrams in all civil law (52) and tax law (23) cases (top 50 unigrams, bigrams and trigrams).
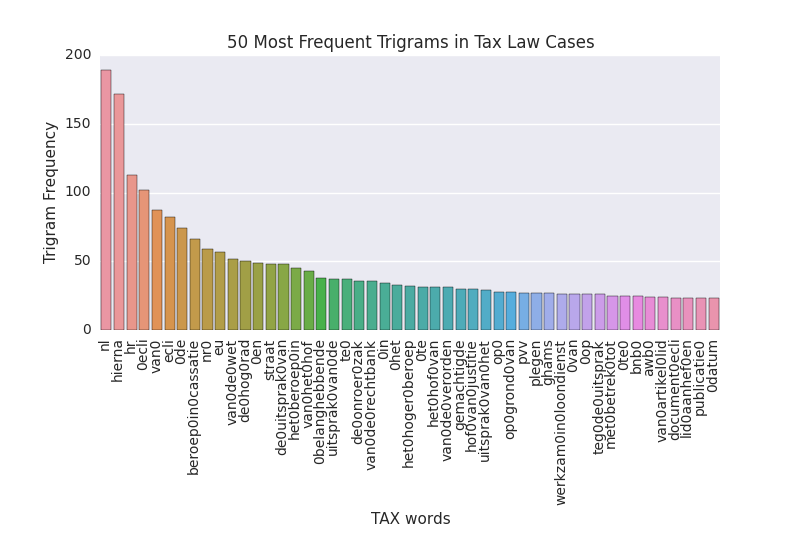
METRIC 5 Trigrams

What Does The Trigram Analysis Reveal?  The main advantage of n-gram analysis is its simplicity. The trigram analysis shows that most tax cases are Supreme Court cases (“beroep in cassatie”, “de hog rad”) and refer more often to precedents (“ecli”), while civil law cases contain more statements concerning the parties (“appellant”, “geïntimeerde”). The unigram analysis shows that demonstrative pronouns (“die”), connectors (“of”), plaintiff (“appellant”), appellate court (“hof”) and lawyer (“advocaat”) occur frequently throughout the corpus.

The tables clearly illustrate the main drawbacks of independent n-gram analyses. The first issue concerns “non-informative” words. Generally, courts use some nouns (e.g.  “plaintiff”, “Court”) and pronouns (“that”, “he”) more often than words that are “informative” because they are only used in a particular subset of cases. For example, the nouns “bankruptcy” or “agreement” are less frequently used in all texts, but may occur more often in a particular subset of the corpus. The second issue concerns synonyms and pronouns. A court may switch between the words “shareholder”,  “he” and “company” while referring to a parent corporation in a corporate group. The third and most important drawback is the loss of context.  Even in the highly unlikely case that courts use only informative words and are consistent in their use of words, n-gram analyses ignore the textual context in which these words appear. The analyst only knows whether the court used the word(s), not how they were used. Yet, one of the most important characteristics of legal rules is that they establish legal relations between legal concepts.

In upcoming posts, I address these issues by adding new layers of legal analytics to the QNL. Feel free to post comments or send me a message!


Posted in Case Law Analysis, Data Science, Dutch Law, Geen categorie, Judicial Behavior, Legal AnalyticsTagged beautiful soup, judicial behavior, rechtspraak.nl, text analytics

QNL #1: Dutch Case Law Brief, October 12-18, 2015

Posted on 10/29/2015 - 01/04/2016 by mtjonakon

In this post, I want to share with you the results of a program involving natural language processing and machine learning tools. The aim of the program is to provide insights into Dutch case law developments on a weekly basis, using case law published on www.rechtspraak.nl. As the program is still in beta, feel free to comment or make suggestions. I use Python as a main language and use several different packages for data analysis and visualization.

1. Number of cases by institution and area of law

I collected the ECLI numbers of all cases published between October 12-18 via site’s API (more info) and downloaded the contents of the cases on a local hard drive. In total, 301 cases were published (list).

Number of decisions by institution
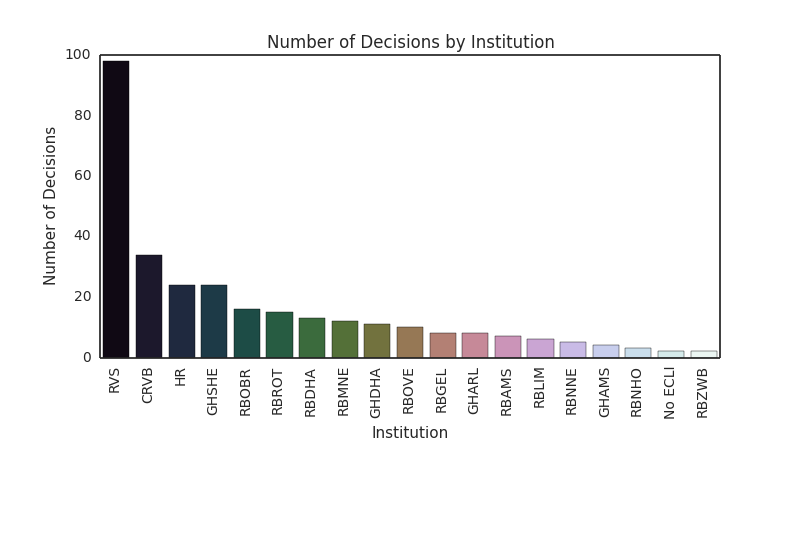
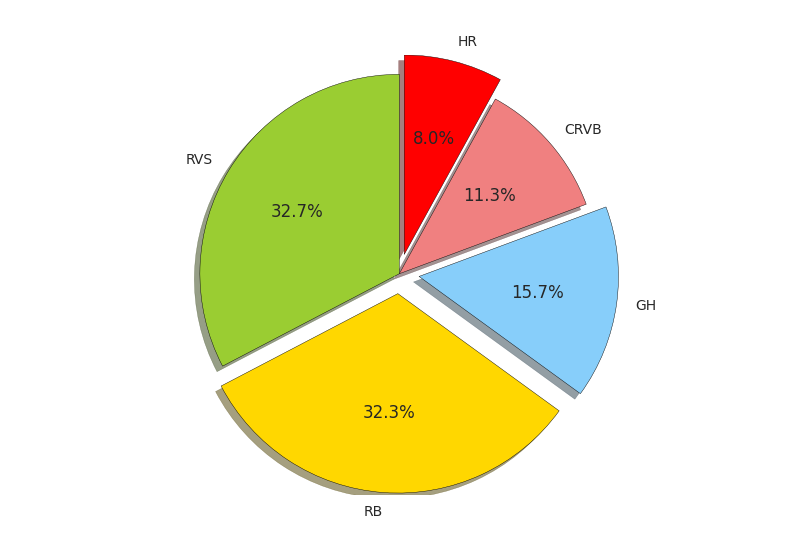
The top 4 institutions (in terms of total cases published) are “Raad van Staete” (RVS, 98), “Centrale Raad voor Beroep” (CRVB, 34), and the Supreme Court of the Netherlands (“Hoge Raad”, HR, 24), tied with “Gerechtshof ‘s-Hertogenbosch” (GHSHE, 24). A comparison by institutional group shows the expected pattern (# decision by lower courts versus HR):
Decisions by Institutional Group
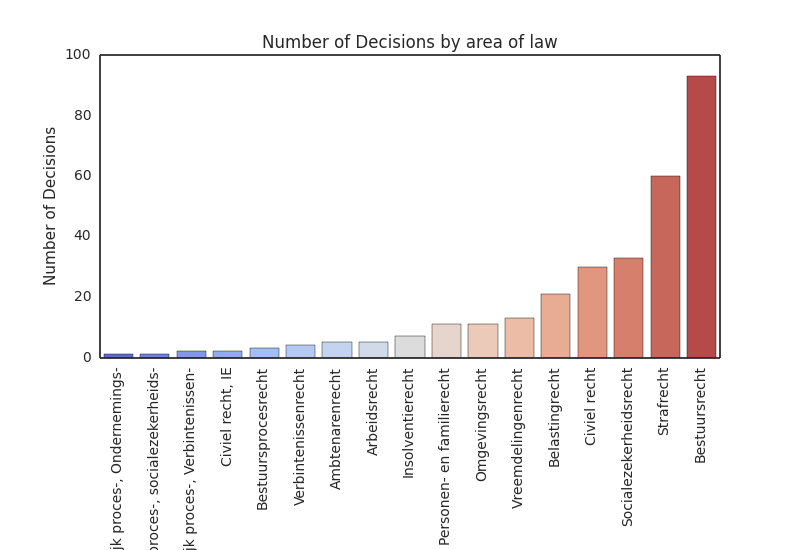
Plotting the distribution of legal areas on the x-axis:
Table 2 - Number of decisions by area of law.
Clearly, the top areas of law are “Bestuursrecht”, “Strafrecht”, “Socialezekerheidsrecht” and “Civiel recht”. I used the classification by area of law as designated by the judiciary in the metaterms of each case. In later reports I intend to develop an alternative, text-based classification.

2. Court-specific metrics: output and throughput

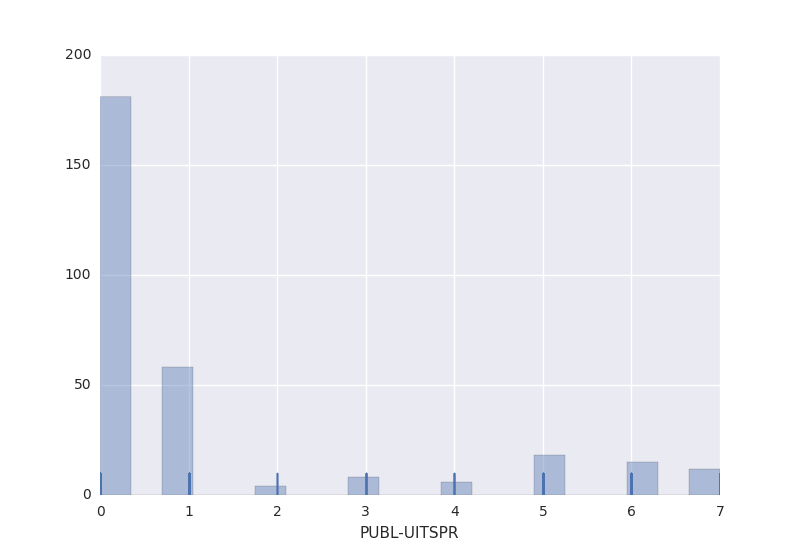
While it would be interesting to analyze the workload of individual courts, rechtspraak.nl does not publish the number of filings at each court. As the United States Courts website illustrates, providing those numbers is feasible. Without filing info, analyzing workload is impossible. Instead, I look at the throughput time: the time it takes the court to publish the decision after issuing the verdict. An interesting question, to consider in the future, is its relation to decision length and case complexity.

Throughput_Hist

In most cases, the decision is published on the same day. There does not seem to be a general relation between the throughput time and area of law (PUB_area) or court (PUB_instantie). More data is needed to unearth the explanation for this distribution.

3. Text features: basic unigram classification

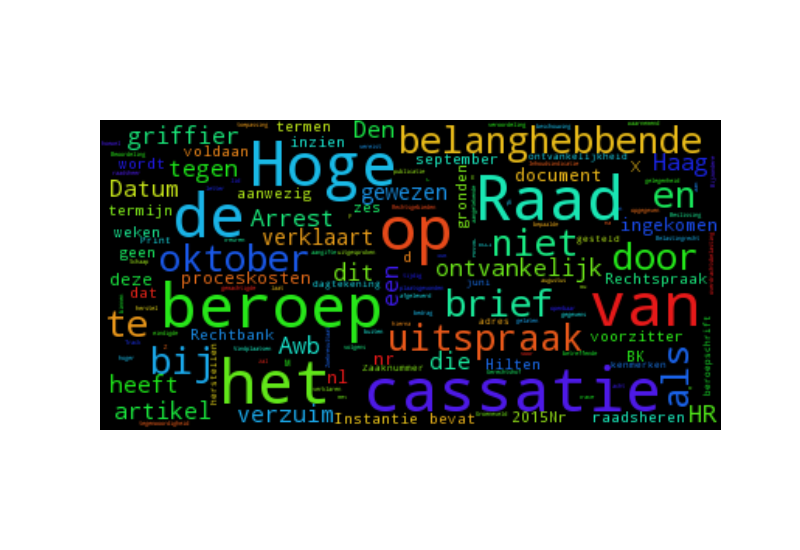
In terms of structure, court decisions are simply long and unstructured text strings. There are numerous natural language processing techniques which facilitate statistical analysis of these text strings by extracting features, some of which I will use in the future (e.g. POS Tag sequences, Hidden Markov Models, Deep Learning, ontologies). In this QNL, I restrict the analysis to “unigrams” or individual words. This bag-of-words approach is simplistic, but suffices for exploratory purposes. After preprocessing (Feldman & Sanger 2007), I count the word frequency for ECLI:NL:HR:2015:3091, a decision issued by the Supreme Court, and posted the result in a word cloud:

CLOUD

The main drawback of the BOW approach is that it assumes a positive correlation between word frequency and relevance. In other words: the more the decision mentions a particular word, the greater the likelihood that word is indicative of the decision’s content. It also performs better if each word refers to an independent concept (i.e. “claimant” does not equal victim), as it disregards that different words may refer to the same legal concept and that different legal concepts may fall in the same general category. For this reason, building and using ontologies (knowledge systems) are crucial in legal text mining.

Next upcoming weeks, I will actually use text classification algorithms with a richer set of features to analyze the decision. Let me know what you think!


Posted in Data Science, Dutch Law, Geen categorie, Judicial Behavior, Legal AnalyticsTagged economic analysis of law, judicial behavior, law enforcement, python, rechtspraak.nl, text analytics

FinCEN MSB Data

Posted on 09/27/2015 - 12/22/2020 by mtjonakon

Mining FinCEN data

In this post I discuss how to use a financial institution’s search engine (FinCEN) and Python to analyze data on  financial market participants.   

how to use a financial institution’s search engine (FinCEN) and Python to analyze data on  financial market participants.   

Legal Background

The Financial Crimes Enforcement Network is a bureau within the Treasury Department, established on 31 U.S.C. §310 as a regulatory basis. Its duties and powers with respect to data analysis include, in short:

  1. advise and make recommendations on matters relating to financial intelligence, financial crimes and other financial activities;
  2. Maintain a government-wide data access service with access to (i) information collected by the Department of the Treasury including reports concerning monetary instruments transactions, pursuant to [several Acts] , (ii) information regarding currency flows, (iii) other records and data maintained by government agencies, among other information;
  3. analyze and disseminate the available data to (i) identify possible criminal activity to enforcement agencies; (ii) support criminal financial investigations, prosecutions and proceedings; (iii) identify possible instances of noncompliance; (v) determine emerging trends and methods in money laundering and other financial crimes; (vi) support the conduct of intelligence activities to protect against international terrorism;
  4. Establish and maintain a financial crimes communications center to furnish law enforcement authorities with intelligence information related to emerging or ongoing investigations and undercover operations
  5.  Furnish research, analytical, and informational services to financial institutions in the interest of detection, prevention, and prosecution of terrorism, organized crime, money laundering, and other financial crimes
  6. Provide computer and data support and data analysis to the Secretary of the Treasury for tracking and controlling foreign assets.

Pursuant to Treasury Order 180-01, FinCEN is responsible for the implementation, administration and enforcement of compliance with
the Currency and Foreign Transactions Reporting Act of 1970 (“Bank Secrecy Act”), a law that requires companies to co-operate with the government to prevent money laundering. Section 1022.380 of 31 CFR Chapter X applies to money services businesses (MSBs) as defined in 31 CFR 1010.100 (ff) and requires these companies to register with the FinCEN. The FinCEN maintains a repository on its website with publicly available information on all MSB Registrants.

Mining HTML tables and analyzing them using Python Pandas

Python, together with the BeautifulSoup and Pandas libraries, makes extracting the MSB data an easy task

FinCEN allows you to either (1) download the .xls file containing all registrants or (2) use the web interface to view (a part or all of) the registrants. Obviously, we will use route (2) since knowing how to scrape the page is a useful skill for websites which do not provide an .xls file.

A brief look at the Document Object Model of the webpage reveals a pretty straightforward HTML structure with an embedded table. Python, together with the BeautifulSoup and Pandas libraries, makes extracting the MSB data an easy task. I posted a simple script here. Note that I first created a local copy of the HTML before scraping it. Navigating the HTML tags allows you to preserve the table’s structure and dump it in a Pandas DataFrame, which you can subsequently use in another program, or export  to csv.

To get a sense of the activities of MSB registrants, I use Pandas. Since FinCEN provides uses numeric codes to refer to the MSB activities, you must use information located elsewhere on the institution’s page to make sense of the data. Using a basic script, I produced the following:

Overview of MSB Activities in all States and Territories.
Overview of MSB activities in all States and Territories.
Overview of MSB activities as disclosed by New York based registrants.

It is relatively easy to sort the bars by size, which I will leave to you. To compare the numbers, I used basic Numpy code to produce a concise table:

msb_sumo1

It seems that in New York State as well in all U.S. States and Territories, cashing checks, transmitting money and selling money orders are the most common activities of MSB registrants. These are not the only activities of the respective MSB registrants, as very often MSBs are engaged in multiple activities and active in multiple States.


Posted in Data Science, Financial Law, Financial Regulation, Geen categorie, Legal Analytics

Innovation within the Dutch Judiciary: New API Service

Posted on 11/17/2014 - 12/22/2020 by mtjonakon

The Board of the Dutch Judiciary keeps on innovating!

Until recently, to find case law one had to use a browser, navigate through cumbersome Java menus and scroll endlessly. With the introduction of the Open Data van de Rechtspraak RESTful web service, you can send requests directly to the server. This means that if you run a simple script from your Terminal (Mac) or Command Prompt (Windows), within seconds you receive the ECLI index numbers of the cases you are looking for. By enabling users to send selection parameters with the requests, the web services allows searches by time period, institution and many other selection criteria.

For lawyers and researchers using Python, I wrote a few lines of code (available here) to automate these search queries. Just download the file, adjust the parameters and run the script using the applicable command  (Mac: just type python rechtspraak_api. py). Note that first you must install the imported libraries. The script uses Python’s BeautifulSoup to strip the case numbers from the server’s XML response and saves them in a text file.

Posted in Geen categorieLeave a comment
Proudly powered by WordPress | Theme: micro, developed by DevriX.